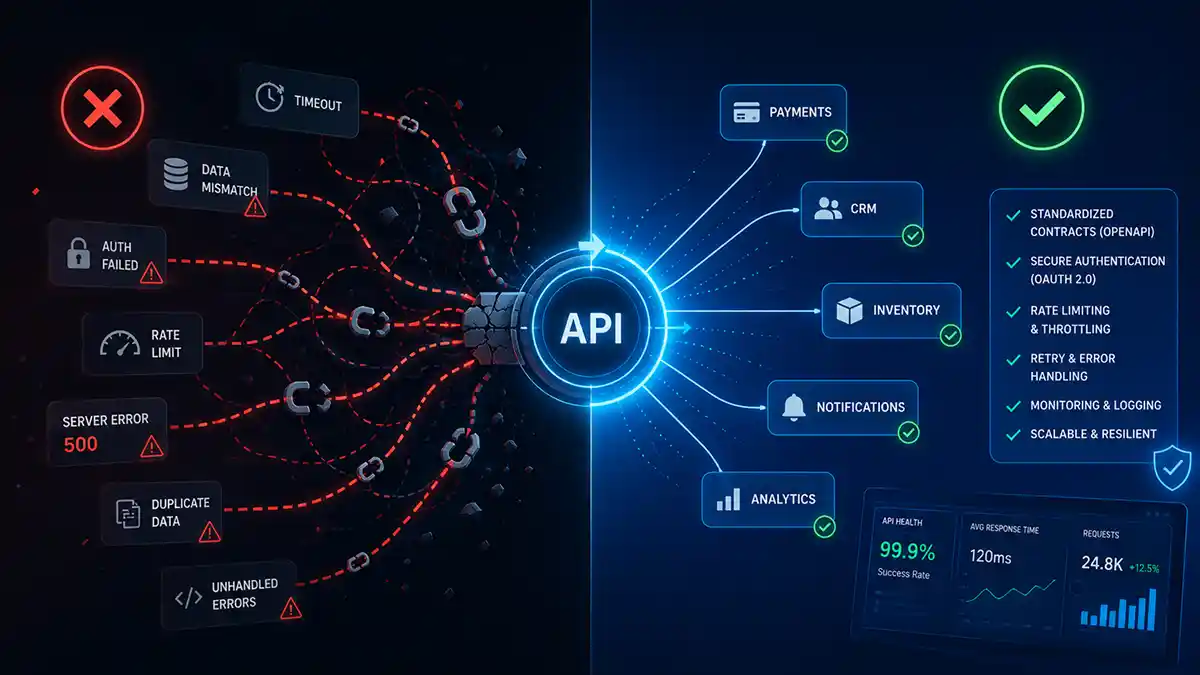
Most API integrations fail not because the API is bad, but because the integration is built optimistically. The happy path works. The edge cases do not.
Here is what we see most often in codebases we inherit.
No retry logic
Third-party APIs go down. Rate limits get hit. Network packets get dropped. If your integration does not handle transient failures gracefully, every outage cascades directly into your product.
Retry with increasing delays and a little randomness, so a recovering service is not hit by every client at the same moment. Retry only what is safe to repeat, and stop after a sensible number of attempts.
No timeouts
A call that never returns is worse than one that fails. Without a timeout, a slow third party ties up your own workers until your product stops responding too. Set a timeout on every outbound call, and stop calling a service for a while when it keeps failing.
Requests that are not safe to repeat
If a payment request times out, did it succeed? Without a way to tell, a retry can charge a customer twice. Send a unique key with every request that changes something, so the other side can recognise a repeat and ignore it.
Tight coupling
When the third-party API changes its schema, your entire data pipeline breaks. The fix is an anti-corruption layer — a translation boundary that absorbs upstream changes without touching your domain model.
In practice, only one module in your code should know what the provider’s data looks like. Everything else works with your own types. Changing provider then means rewriting one module, not the application.
No versioning strategy
APIs deprecate endpoints. If you are not pinning to a specific API version and monitoring deprecation notices, you are building on sand.
Trusting webhooks blindly
Webhooks arrive late, out of order, more than once, and sometimes not at all. Verify the signature, acknowledge quickly and process in a queue, handle duplicates, and run a periodic reconciliation that fetches the truth from the API to catch anything missed.
Ignoring rate limits and pagination
An integration that works with ten records can fail with ten thousand. Respect the provider’s rate limits, page through large results, and move bulk work into background jobs instead of doing it during a user request.
No observability
You find out the integration is broken when a customer complains, not from a dashboard. Every integration should emit structured logs and fire alerts on failure rates above a threshold.
Log each call with its duration and result, without recording secrets or personal data, so you can answer “what happened to this order?” in minutes.
Test the failures, not just the successes
Use the provider’s sandbox, and add tests that simulate timeouts, error responses, malformed data and duplicate events. If your tests only cover the happy path, so does your integration.
A checklist before you ship
- Timeouts and bounded retries on every call.
- Requests that change data are safe to repeat.
- Provider data is translated at one boundary.
- API version pinned; deprecation notices monitored.
- Webhooks verified, de-duplicated and reconciled.
- Credentials stored securely and rotated.
- Logs, metrics and alerts in place.
Build integrations with the assumption that the third party will let you down. Design for it. Test for it. Your users will never see the difference.
Need an integration built or rescued? See our software development services or hire senior backend engineers.